
Major Announcement: Step 5 Preview Launched
- Release Date: September 20, 2026
- New Version: Step 5 Preview (full release opensourced on October 15)
- Availability: Preview available now; full model opensourced October 15
- Open Weights: Yes, fully open-sourced
- Architecture: Sparse Mixture of Experts (MoE)
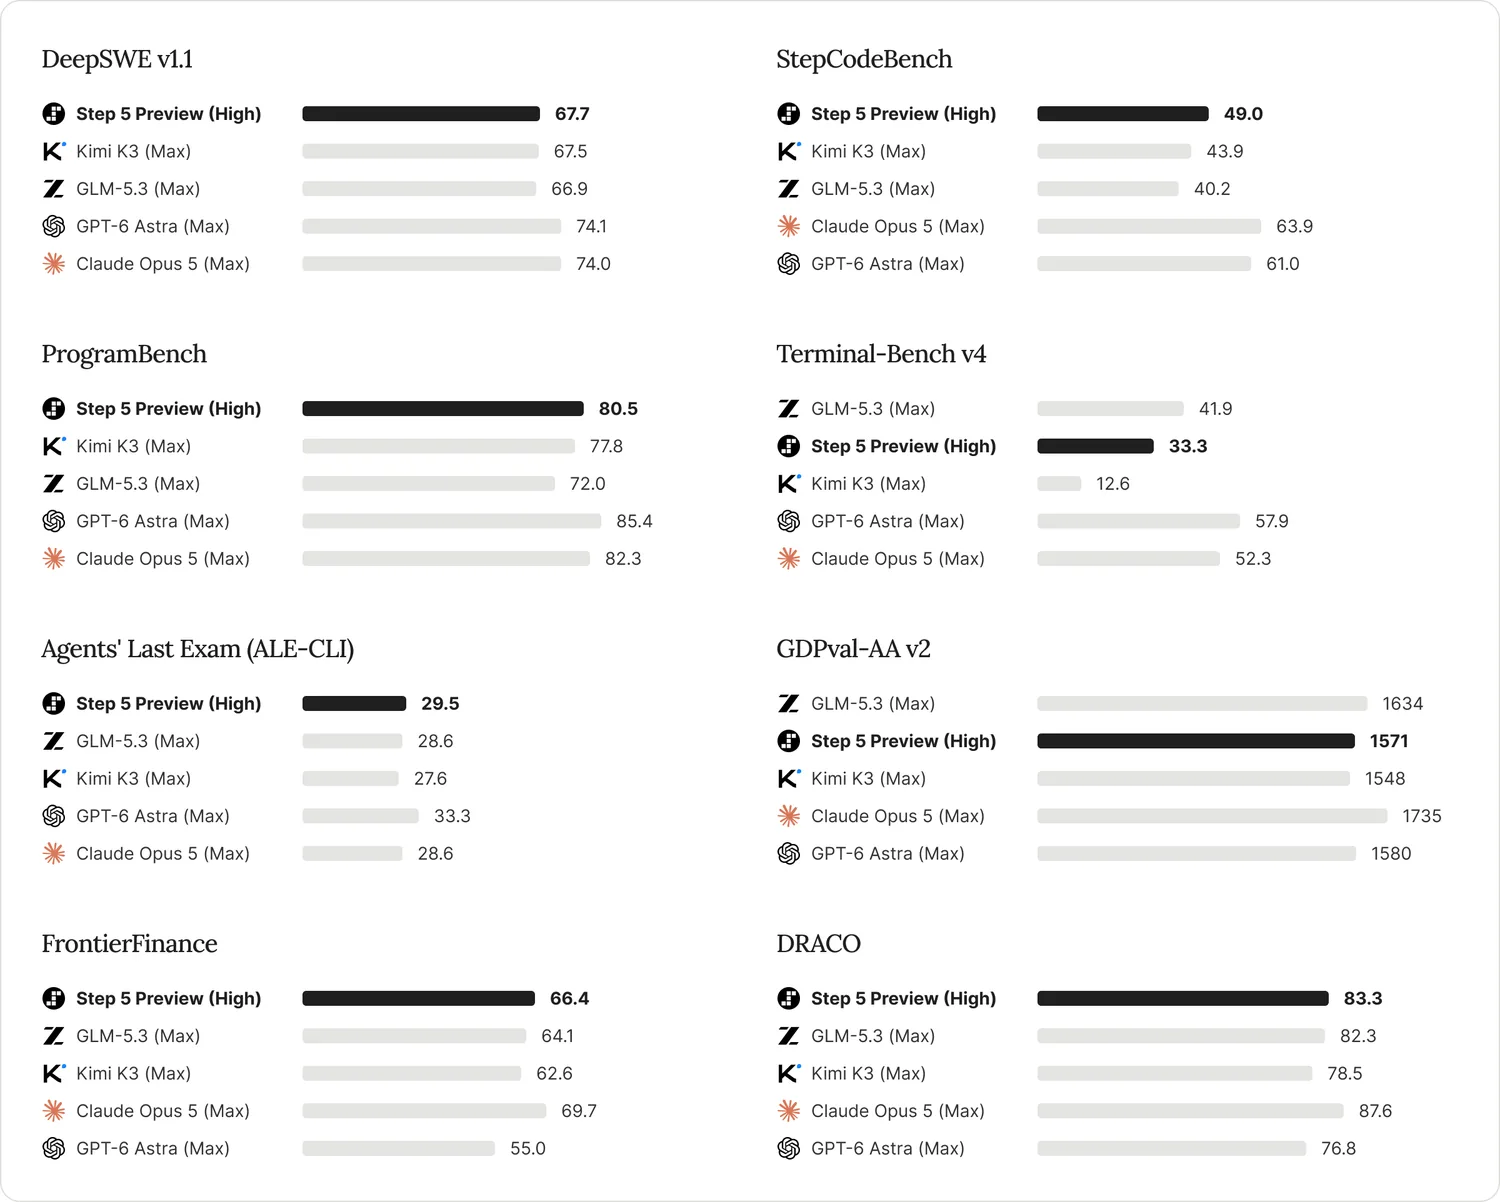
Stepforward AI unveiled its new flagship base model, Step 5 Preview, on September 20. The model targets real-world Agentic tasks in AI programming, software engineering, professional knowledge work, and finance. Its core promise is optimizing the trade-off between intelligence, cost, efficiency, and scenario coverage.
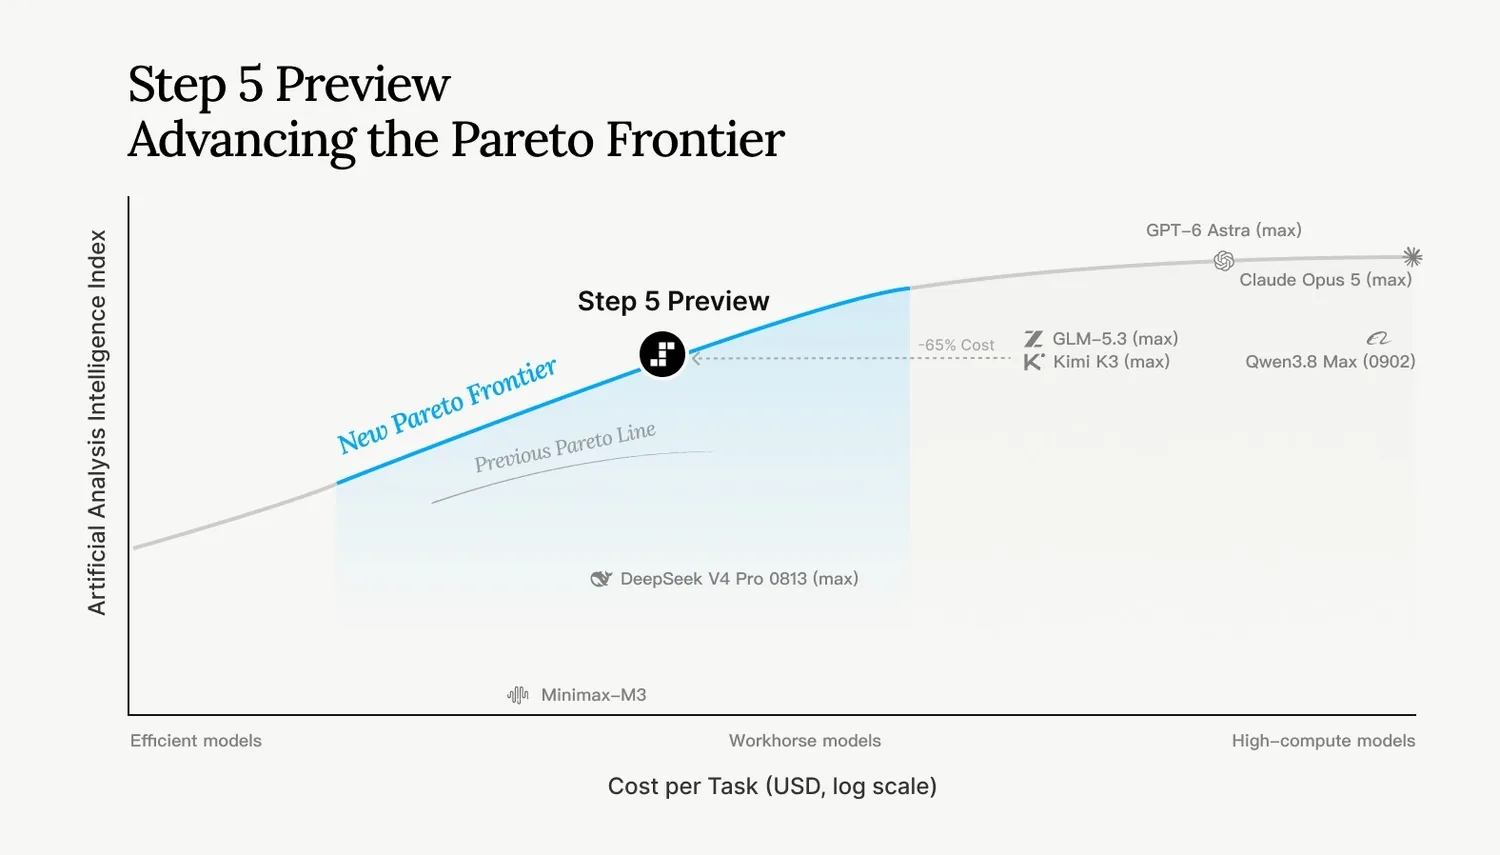
The standout claim: Step 5 Preview delivers single-task performance at only 1/8th the cost of Claude Opus 5. This cost-per-intelligence ratio positions it as a compelling option for production workloads demanding both capability and affordability.
Technical Specs and Benchmarks
Built on a sparse Mixture of Experts (MoE) architecture—where only a subset of “expert” sub-networks activates per inference—the model packs 600B total parameters with just 27B activated per token. This design achieves high capability without proportional compute overhead.
Key specs:
- Context Window: 1 million tokens
- Modality Support: Native text and visual input
- Use Cases: Software engineering, financial modeling, professional workflows
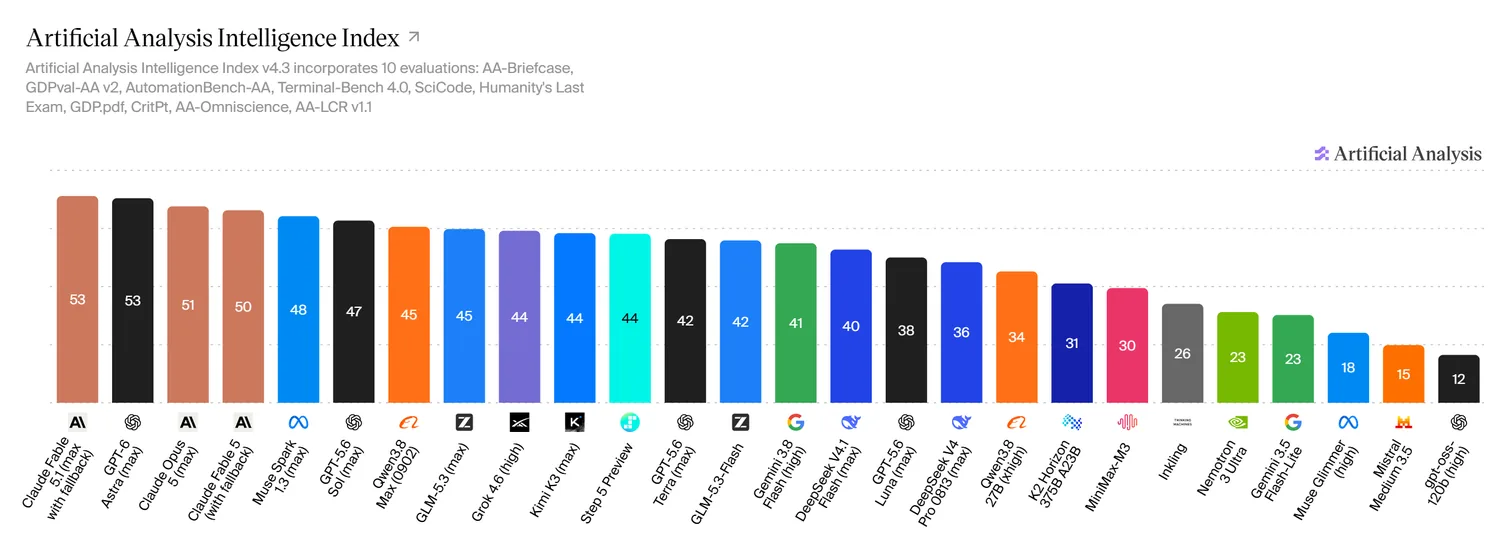
On the Artificial Analysis Intelligence Index (AA Index), a global benchmark for AI capability, Step 5 Preview ranks top-3 among open-weight models. This places it alongside elite closed-source systems while maintaining full openness—a rare feat.
Performance vs. Cost Comparison
| Model | Architecture | Total Params | Activated Params | Context Window | Cost (Relative) | AA Rank (Open) |
|---|---|---|---|---|---|---|
| Step 5 Preview | Sparse MoE | 600B | 27B | 1M tokens | 1× | Top-3 |
| Claude Opus 5 | Proprietary | Unspecified | Unspecified | Unspecified | 8× | — |
Contrast Point: Despite 600B total parameters, only 27B activate per task, explaining the efficiency. Traditional dense models would require significantly more energy and hardware to match this level of capability.
Use-Case Fit
Step 5 Preview’s value proposition centers on scaling efficiency: “using less compute for more intelligence.” This philosophy appears consistent across three consecutive generator iterations (Step 3.5 Flash → 3.7 Flash → 5 Preview).
The model targets Agentic workflows—autonomous, multi-step task handling—where sustained performance over long horizons matters more than peak single-turn accuracy.
Practical Adoption Advice
- Try Now If: You’re building AI agents, automation pipelines, or coding assistants; cost sensitive but need strong reasoner capacity; or want to experiment with open-weight alternatives before production lock-in.
- Wait If: Your use case demands regulatory compliance only闭源 vendors can offer (e.g., healthcare diagnostics); or if you require enterprise SLAs + support Guarantees. Evaluate community feedback post-October 15 release.
Final Thoughts
The convergence of open weights, high benchmark scores, and sharp cost reductions proves that scaling efficiency—not just scale—is now the decisive metric for state-of-the-art AI. As open models close the capability gap, real-world deployment economics finally catch up with technical promise.