Core Announcement
In September 2026, Diogo Almeida—former OpenAI researcher and co-inventor of ChatGPT—launched Jev through his startup TypeSafe AI. The model cannot generate text or punctuation and delivers only deterministic structured decisions. It is currently in limited closed-beta access, backed by $40 million in funding.
- Release date: September 2026
- New version: Jev (the world’s first pure ‘System One’ model)
- Availability: Limited closed-beta by invitation
- Weight openness: No specific architecture or training details disclosed
- Core feature: Non-text generation, single-pass parallel computation output, strictly locked to pre-defined schemas
Counterintuitive Technical Approach
While mainstream large models have focused on ‘System Two’—slow, reasoning-intensive thinking—TypeSafe has taken the opposite path, defining Jev as the world’s first pure ‘System One’ model that prioritizes unconscious, rapid, instinctive decision-making.
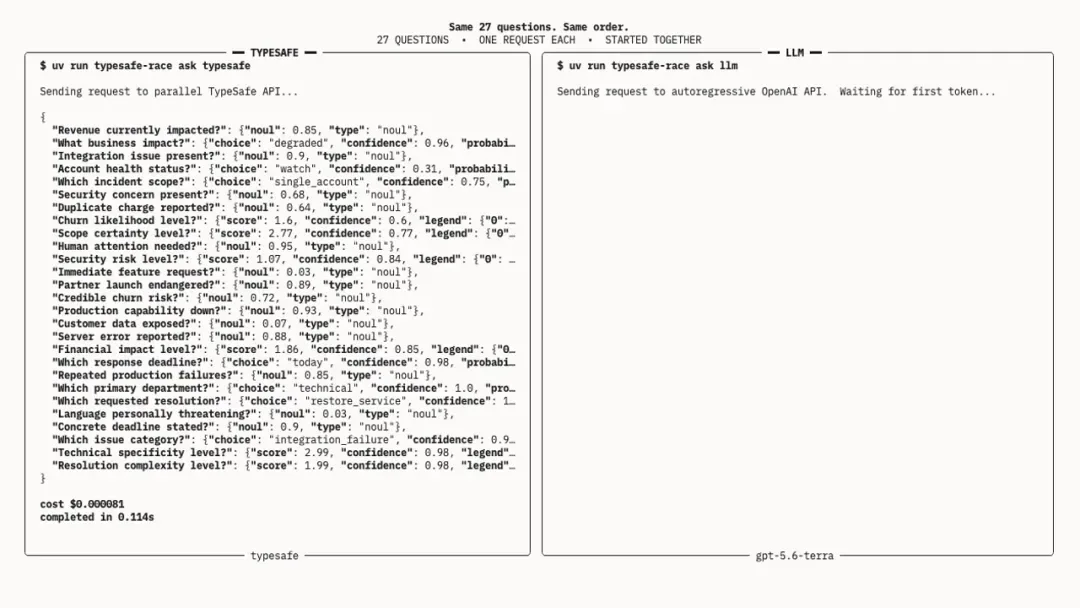
Jev’s output mechanism diverges fundamentally from traditional autoregressive models: rather than generating tokens sequentially over time, it produces all decision components simultaneously in a single forward parallel computation. This means:
- No generative overhead: Output is strictly constrained to developer-defined schemas, eliminating format hallucinations entirely
- End-to-end latency of 70–500 milliseconds: 40–200x faster than leading large models
- Free output generation: Input costs only $0.042 per 1 million tokens
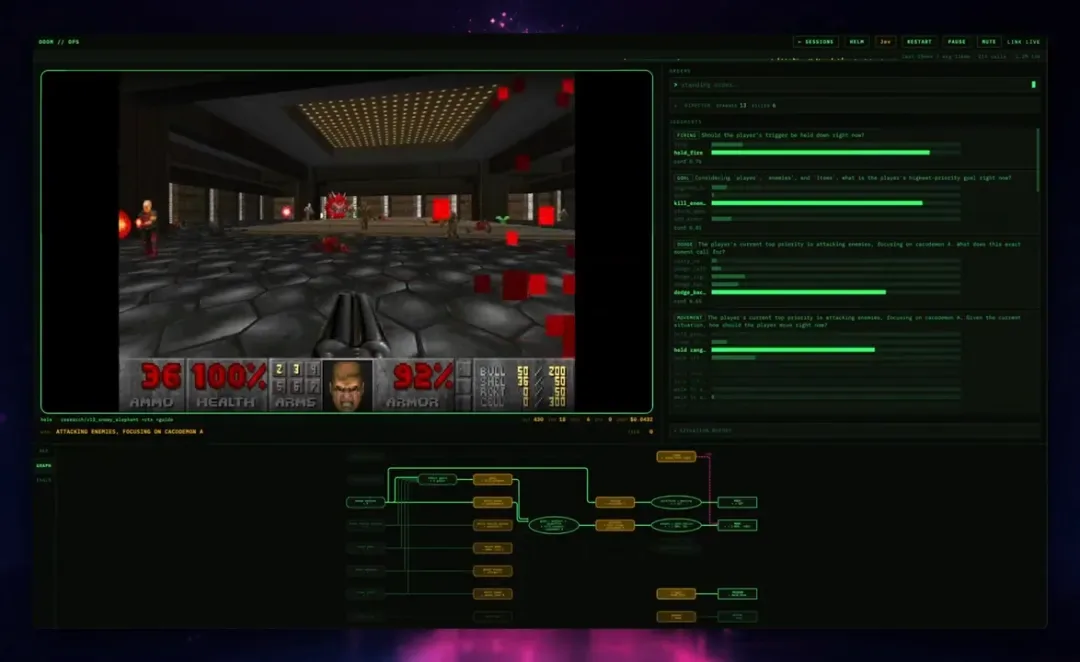
In Doom game testing, Jev achieved approximately 10 real-time decisions per second at a cost of about $7 per hour. Most striking is the price-performance ratio: a single structured decision averages $0.0004, roughly 1/76 the cost of GPT-5.6 Terra and several hundred times cheaper than Claude Opus 5.
Real-World Industrial Applications
TypeSafe emphasizes Jev is designed not to replace frontier models but to fill the ‘reflection arc’ gap in their system architecture. In typical Agent workflows, dozens of decision nodes—if each invokes a billion-parameter model—accumulate delays, escalate costs, and risk JSON parse failures.
Across four enterprise workflow benchmarks, Jev achieved 67.8% accuracy, nearly matching GPT-5.6 Terra’s 67.9%, while executing dozens of times faster. This validates its positioning: let expensive frontier models serve as System Two for high-level planning, while delegating high-frequency, low-complexity judgments to Jev’s millisecond-speed reflexes.
| Model | Input cost (per 1M tokens) | Output cost | Cost per decision | Relative to GPT-5.6 Terra |
|---|---|---|---|---|
| Jev | $0.042 | Free | $0.0004 | 1/76 |
| GPT-5.6 Terra | ~$0.03 (estimated) | Estimated fee | ~$0.03 | baseline |
| Claude Opus 5 | Estimated higher | Estimated fee | hundreds x Jev | hundreds x |
Implementation Guidance
Jev is particularly well-suited for:
- High-frequency decision nodes: ticket classification, content moderation screening, large-scale data labeling
- API routing and tool selection: quickly determining which interface to invoke among multiple options
- Real-time response systems: game agents, high-frequency trading signals, robot immediate control actions
Enterprises should first validate Jev’s reliability and tolerance for its missing interpretability in non-critical paths. Strongly regulated sectors—finance, healthcare, legal—must proceed cautiously: Jev cannot explain its reasoning in natural language and lacks auditability, potentially colliding with compliance requirements.
Final Thought
Jev’s emergence exposes the ’execution friction’ bottleneck in current AI Agent architectures. While the industry spent three years racing to lengthen reasoning chains, its counter-path proves that speed and determinism can sometimes matter more than linguistic expressiveness. However, its closed evaluation methodology and business model sustainability remain unproven at scale.