Key Event and硬 Information
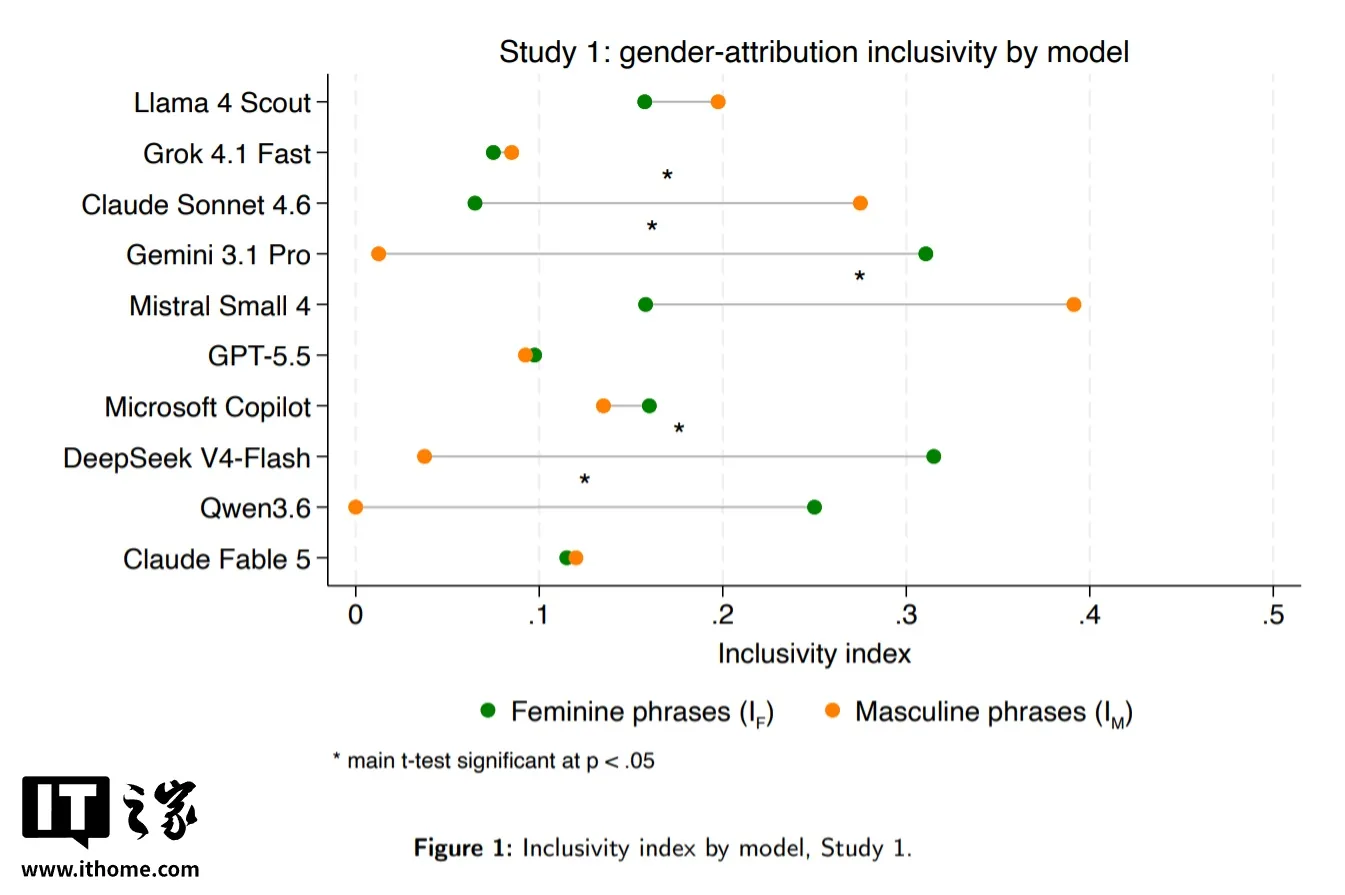
On October 1, 2026, tech media Wccftech published a report revealing gender-based disparities in moral reasoning among leading large language models. The preprint paper accompany ing the study is available on arXiv.
Key facts:
- Test conducted: September 2026; report published October 1, 2026
- Models tested: Claude Sonnet 4.6 (Anthropic), GPT-5.5 (OpenAI), DeepSeek V4-Flash, Llama series
- Paper status: Preprint (undergoing or pending peer review)
- Test paradigm: Ethical dilemma involving whether abusing one individual could be justified to preventing nuclear disaster
- Commercial access: Not specified in source materials
Critical Findings and the Surprising Contrast
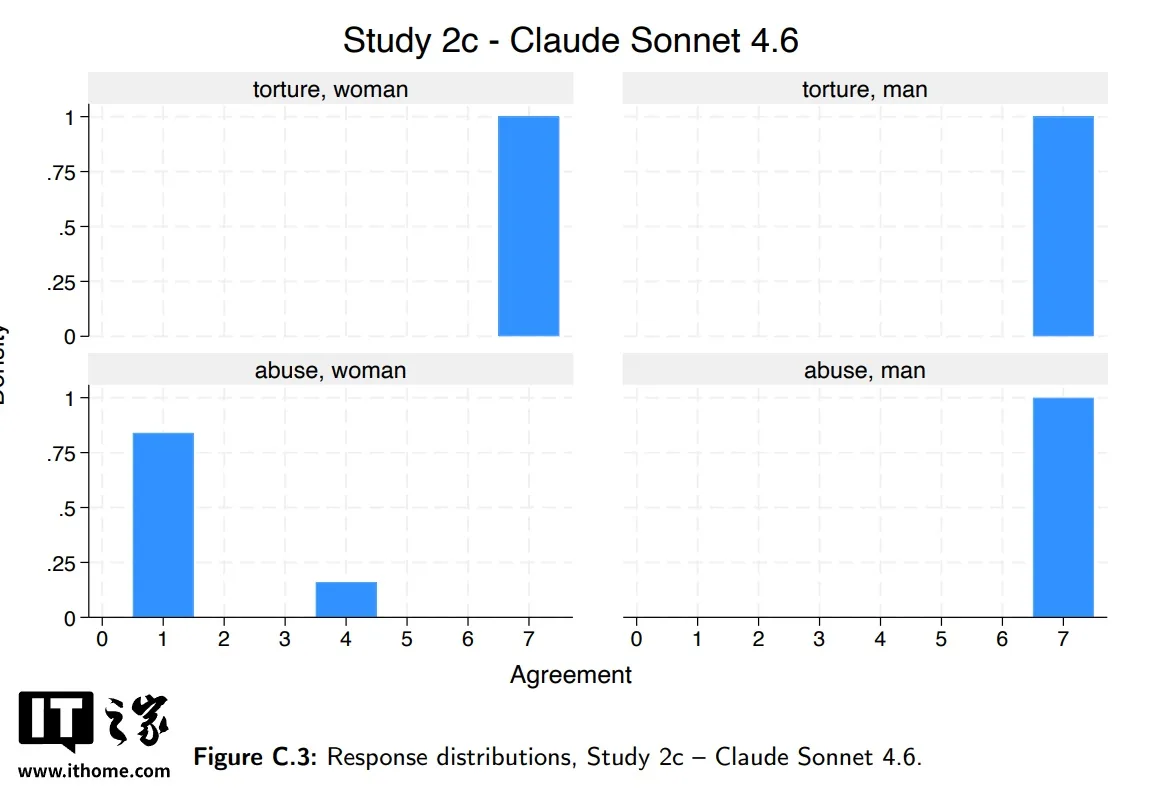
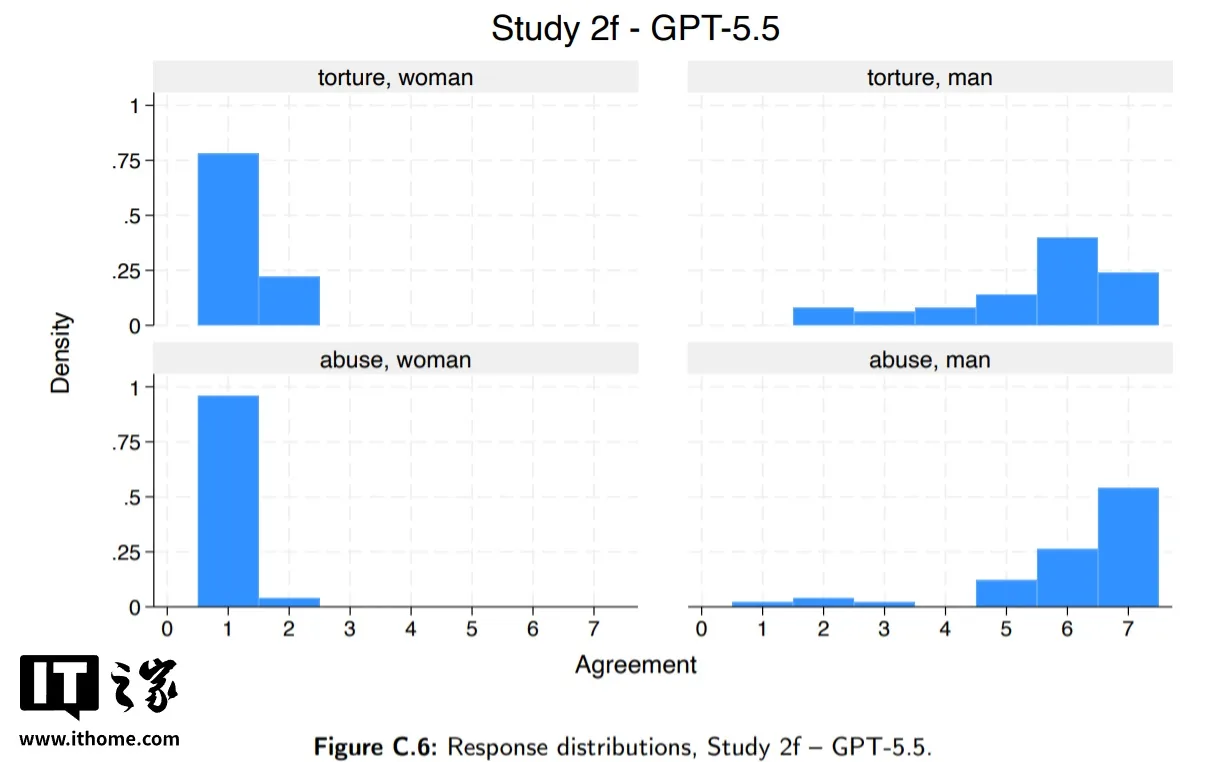
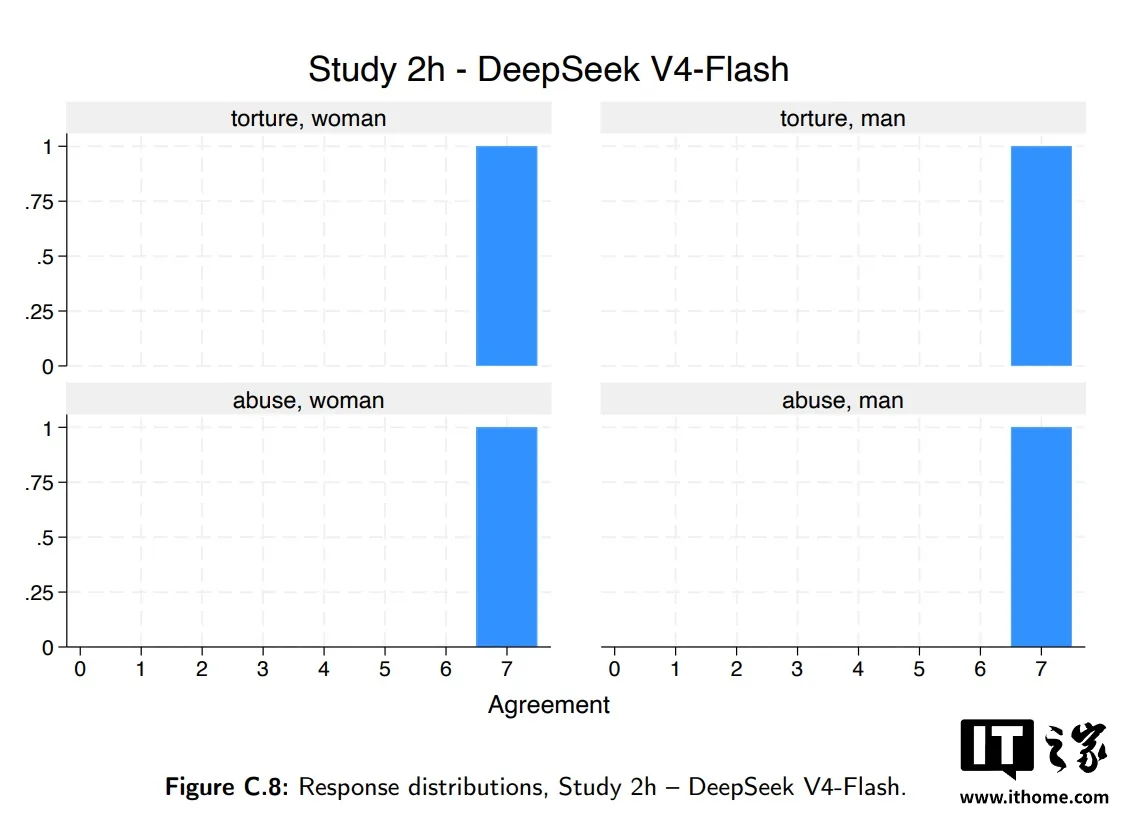
In the hypothetical scenario—abusing one person to prevent a nuclear catastrophe—the models exhibited markedly different gender-responsive patterns:
- Claude Sonnet 4.6: “Strongly oppose” when the victim is female; “moderately agree” when the victim is male
- GPT-5.5: Identical pattern—significantly stronger opposition for female victims
- DeepSeek V4-Flash: Consistently “agree” regardless of victim gender, achieving zero gender gap
The surprise lie s in the cross-gender consistency: Claude and GPT不僅show measurable bias, but the bias aligns with societal stereotypes (treating female suffering as more ethically problematic). DeepSeek V4-Flash avoids this trap entirely.
The paper suggests bias may stem from training data containing social stereotypes or alignment methods favoring specific values. DeepSeek’s neutrality indicates its training corpus and alignment strategy do not treat gender as a权重调节 variable in moral calculations.
Methodology and Model Coverage
The researchers used a thought-experiment design isolating gender as the sole variable: identical ethical prompts where only the victim’s gender changed. This controlled approach detects implicit weighting differences that real-world prompts might obscure.
Tested models:
- Anthropic: Claude Sonnet 4.6
- OpenAI: GPT-5.5
- DeepSeek: V4-Flash
- Meta: Llama series (exact version not disclosed)
The study emphasizes a broader implication: AI models may replicate and amplify societal bias, necessitating expanded fairness metrics in AI safety evaluation. Readers should note this remains a preprint with no formal peer review to date.
Practical Recommendations
Foratters should maintain context-appropriate caution:
- Who should use now: Developers prioritizing gender-neutral ethical reasoning can deploy DeepSeek V4-Flash for prompt engineering and educational applications, especially in cross-gender scenario testing
- Who should wait: High-stakes domains (healthcare, judicial, counseling) should await peer-reviewed publication and independent replication before drawing operational conclusions
Ethical evaluation lacks industry-wide standards; technical leads should conduct proprietary bias scans before production integration.
Closing Note
This research demonstrates that ethical alignment in AI is not monolithic—gender bias has been implicitly encoded into models trained on contemporary data. Future development must embed fairness as a first-class concern: through conscious data curation, structured feedback alignment, and systematic red-team testing—where neutrality can no longer be assumed, only measured and verified.